Reflex Harness
AGENT HARNESS ENGINEERING

Coding agents
get stuck in loops.

Reflex notices when an agent repeats a failed strategy, then changes its working context using evidence from earlier attempts.

A MongoDB-powered harness for persistent, measurable software development. Built for agents that need to recover, not just retry.

GET STARTEDPYTHON CLI
$git clone https://github.com/OlegSavchuk/reflex-harness.git && cd reflex-harnessCLONE
$python -m reflex_harness run --task sem-dev-01 --arm memoryRUN DEV TASK
After README setup: install deps, configure Atlas + model keys, seed memory · Python 3.10+
REFLEX AGENT / LIVE SIGNAL
01 / 07THE AGENT RECOVERY LOOPREFLEX · 2026
01 / 07BUILT WITH
MongoDBVoyage AIOpenRouterTypeSafe AIpytest
01ControllerOwns the attempt loop
02EvidenceTests and attempt history
03ContextSelected from what worked
04RecoverySwitch before the next retry
02 / 07WHY THIS MATTERS

The loop is real. So is the cost.

Ilya Sutskever described the failure pattern plainly: one fix introduces another bug, and repairing that bug brings the first one back.

“
You tell the model can you please fix the bug — and it introduces a second bug. Then you tell it you have a second bug and it brings back the first. You can alternate between those.
Ilya SutskeverCo-founder, OpenAI · SSI
Watch the original YouTube Short ↗
FROM THE ORIGINAL CLIP00:35
Open the Short on YouTube ↗
01

Detect repetition

Compare the latest attempt with prior failures to catch strategy oscillation.
02

Change context

Select from context configurations with evidence of success on similar failures.

03

Keep the record

Store attempts and outcomes so each decision can be inspected and measured.

03 / 07WHAT REFLEX DOES

A harness around the agent.

01 REFLEX IS
  • A controller that owns the attempt loop
  • Context selection based on recorded evidence
  • Bug fixing against a fixed test suite
  • A single process: CLI and dashboard
  • A harness that can adapt its own environment to the task
02 REFLEX IS NOT
  • A new coding model
  • An LLM guessing which prompt might help
  • A feature builder without a test signal
  • A VS Code extension or MCP tool
  • A tool the agent must remember to call
04 / 07SYSTEM ARCHITECTURE

How the control loop works.

Every attempt is observed, recorded, and used to select the next context. The loop runs until a verified fix lands or the budget is spent.
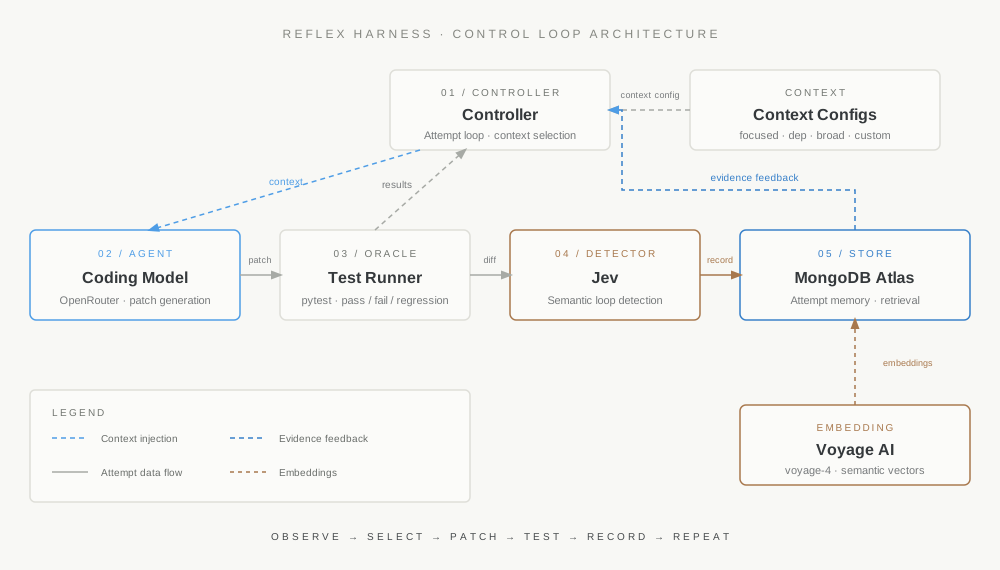
Reflex Harness architecture diagram: Controller selects context, Coding Model generates a patch, Test Runner evaluates it, Jev detects semantic loops, MongoDB Atlas stores attempt memory, Voyage AI provides embeddings. Evidence flows back to the Controller.
GATE 8 HELD-OUT FEASIBILITY EVALUATION

Verified fixes across four held-out tasks.

60RUNS4 TASKS 5 REPEATS
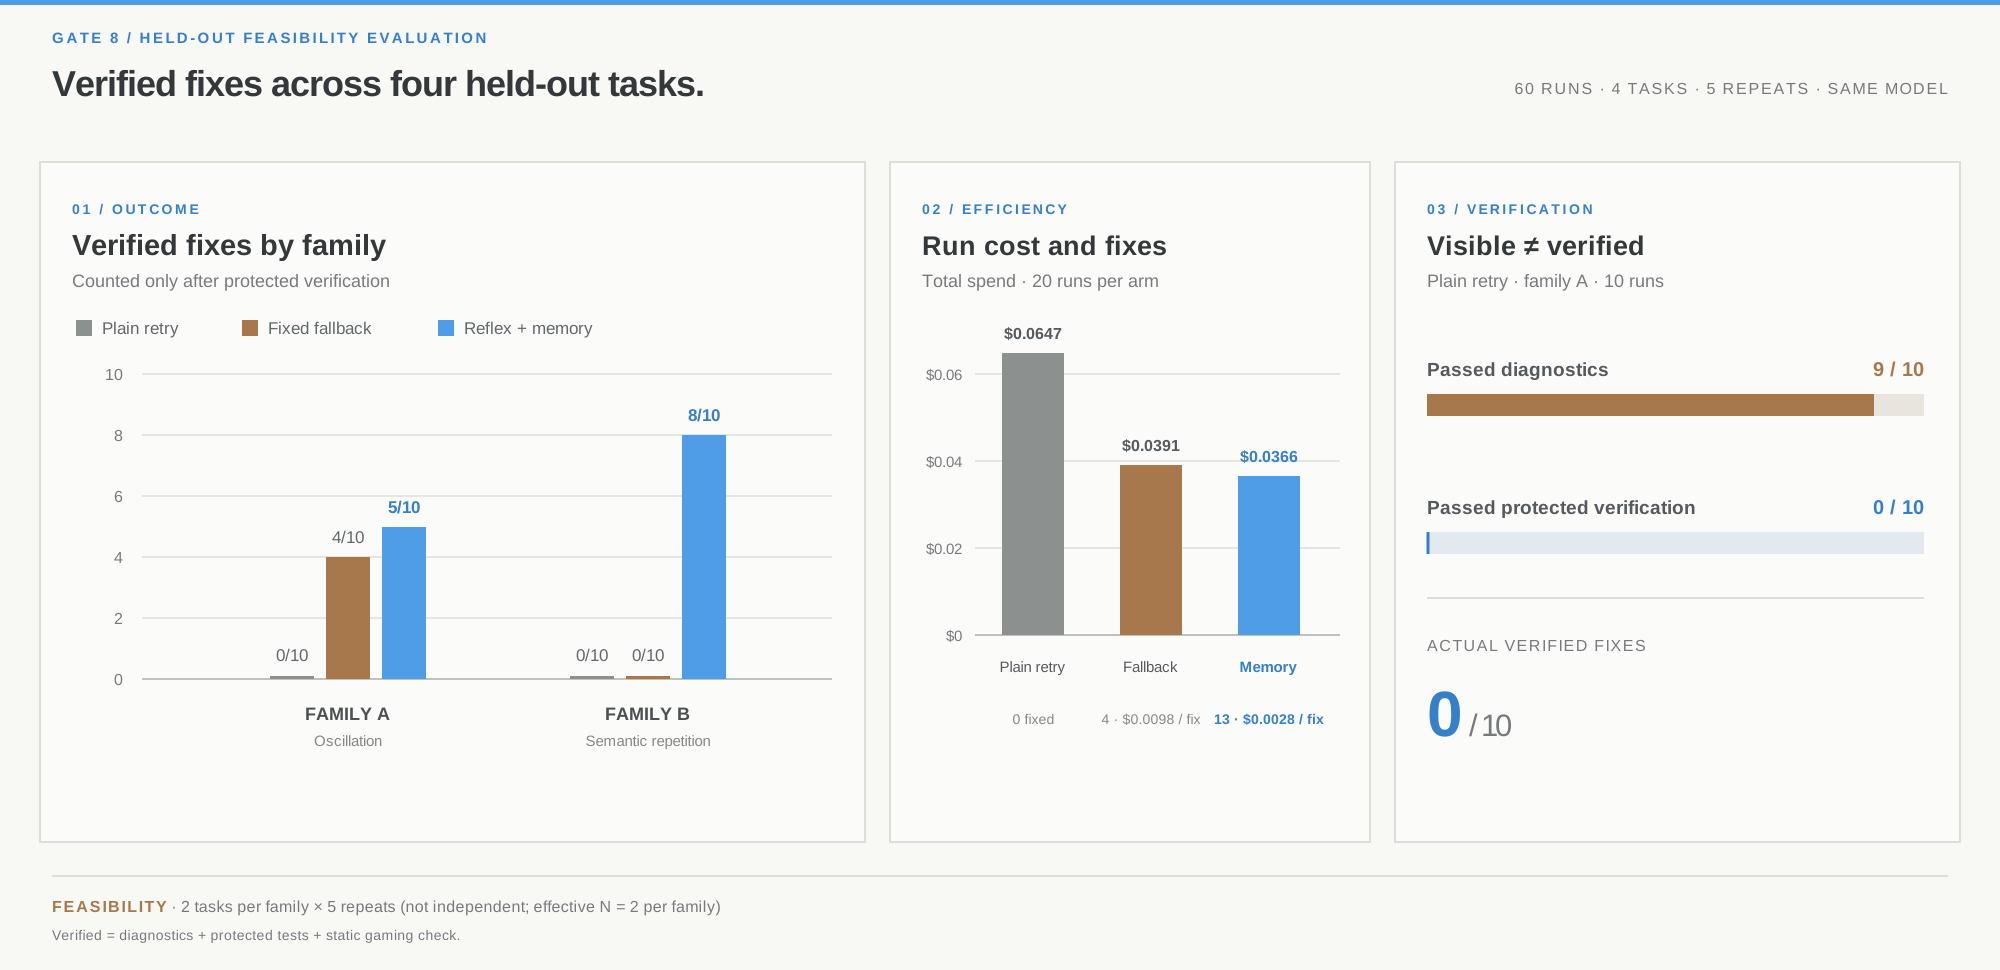
Gate 8 results: Reflex with memory verified 5 of 10 fixes for oscillation and 8 of 10 for semantic repetition, 13 of 20 overall, at $0.0366. Fixed fallback verified 4 of 20 at $0.0391. Plain retry verified 0 of 20 at $0.0647. In family A, 9 of 10 plain retry runs passed diagnostics but none passed protected verification.
01 / BASELINE

Plain retry

0/20verified fixes
Oscillation0/10
Semantic repetition0/10
Run cost $0.0647Per verified fix —
02 / FIXED ORDER

Fixed fallback

4/20verified fixes
Oscillation4/10
Semantic repetition0/10
Run cost $0.0391Per verified fix $0.0098
03 / MEMORY GUIDED

Reflex + memory

13/20verified fixes
Oscillation5/10
Semantic repetition8/10
Run cost $0.0366Per verified fix $0.0028
VERIFIED FIX

Diagnostics, protected tests, and the static gaming check all passed.

01 / SAMPLE

Two held-out tasks per family, repeated five times. Repeats share tasks, so effective N is 2 per family. This is feasibility evidence, not a significance claim.

02 / COMPARISON

Fixed fallback cannot expose family B’s hidden helper. The fair random-choice reference (about 3.3/10) is analytical; it was not run.

03 / SCOPE

Gate 8 measures strategy selection. It does not establish repeated-strategy detection on semantic-repetition tasks.

05 / 07UNDER THE HOOD

An attempt, with evidence at every step.

01

Controller

Selects a context configuration from prior outcomes on similar failures.

→
02

Coding model

Receives the assembled context and returns a patch.

→
03

Test runner

Runs pytest and records passes, failures, and regressions.

→
04

Jev

Checks whether a changed diff repeats a failed strategy.

→
05

MongoDB Atlas

Stores attempts and retrieves the evidence for the next selection.

THE CONTROL LOOPOBSERVE → SELECT → TEST → REMEMBER
06 / 07TOOLS AND STACK

MongoDB is part of the control loop.

MongoDB Atlas 8.0

Attempt memory · retrieval · selection

↗

Voyage AI · voyage-4

Semantic embeddings

↗

OpenRouter

Model routing

↗

Jev 1.13

Semantic loop detection

↗

pytest

Test oracle

↗
i

Reflex is an open source hackathon project. See the repository for setup details, current requirements, and implementation notes.

Repository ↗
07 / 07 SHIP IT

Break the loop.
Keep the evidence.

Explore reflex-harness↗
Reflex HarnessOPEN SOURCE · HARNESS ENGINEERINGGITHUB ↗